In brief
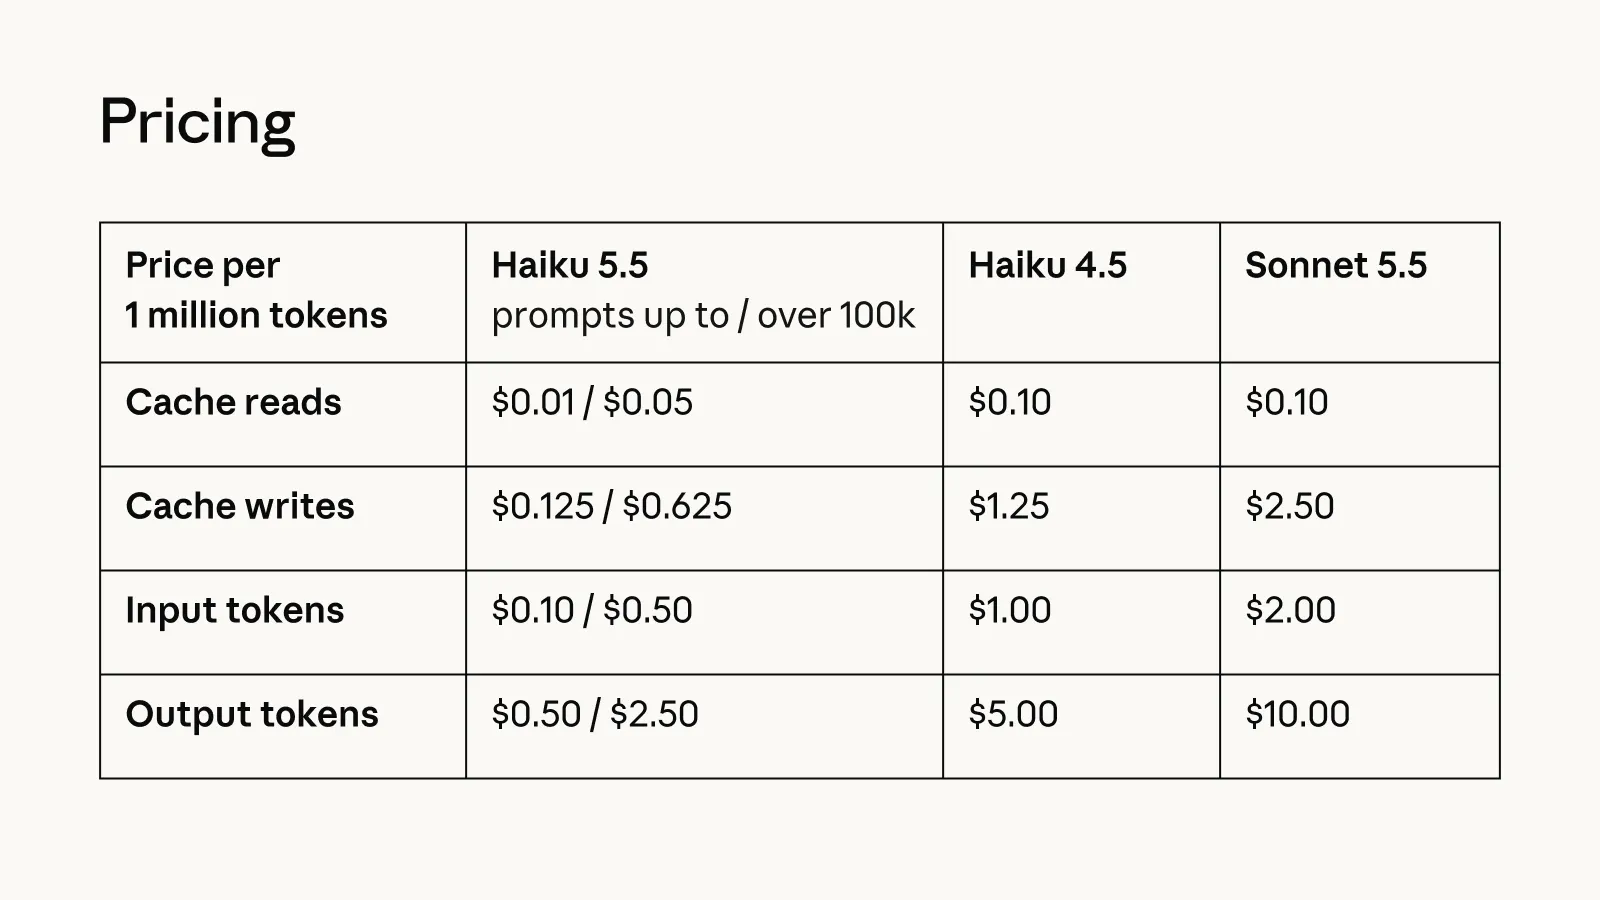
- Anthropic released Claude Haiku 5.5 at $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens, down from $1 and $5 for Haiku 4.5.
- Haiku 5.5 scored 72.4% on the OSWorld 2.1 offline subset and 39.2% on Terminal-Bench 4.0, ahead of OpenAI's GPT-6 Luna on both but well behind Sonnet 5.5's 70.6% on the coding test.
- Anthropic also halved Sonnet 5.5's cache-read price to $0.10 per million tokens and is adding monthly API credits for Max and Team subscribers this week.
Anthropic released Claude Haiku 5.5 on Wednesday, calling it the cheapest, fastest and most capable small model it has made. It targets high-volume chores such as summarizing documents and querying databases, plus speed-sensitive jobs like live customer support and operating a web browser for the user.
Developers who plug Claude into their own products pay $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens. Tokens are the small chunks of text, roughly three-quarters of a word, that AI models read and write—and they’re what big AI companies bill by. That matches the rate OpenAI set for GPT-6 Luna, its rival small model, when it launched on September 22.
Haiku 4.5 charged $1 and $5, so the new rate is 90% lower, while prompts above 100,000 tokens get a 50% cut. Since about 90% of requests to the old model fell under that line, and Haiku 5.5 splits text into slightly more tokens, Anthropic puts the average saving near 75%.
Customer-support chats and long-email summaries are the jobs Anthropic built Haiku for. So essentially repetitive, easy, non creative tasks are the best fit for this model.
That said, benchmarks show this is not a dumb model by any means. For example, on OSWorld 2.1, a test of whether an AI can operate a real computer through long, multi-step tasks, scored as a partial-credit percentage, Haiku 5.5 beats OpenAI’s GPT Luna scoring 72.4% success rate vs 48.9%.
Terminal-Bench 4.0 hands AI agents professional tasks to finish by typing commands on their own, and scores the share completed correctly on the first attempt. Haiku 5.5 landed at 39.2%, against 16.4% for OpenAI’s Luna and 0% for Haiku 4.5
For comparison, Anthropic’s Claude Sonnet 5.5 scored 70.6%.
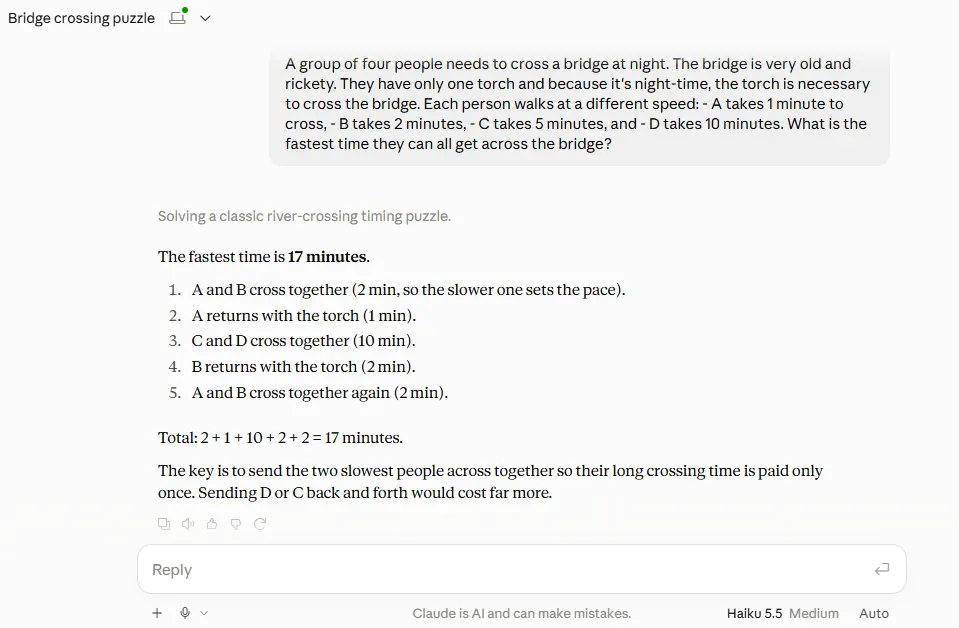
We tried the model on a simple logic question and it was extremely fast to respond, almost instantly. It also gave the wrong answer, which is not what you want from a model, so be careful about blindly trusting it.
On GDPval-AA v2.1, which rates models on real professional work across 44 occupations using an Elo scale, the head-to-head rating system borrowed from chess, Haiku 5.5 scored 1620. Luna got 1437 and Haiku 4.5 got 735.
This is also the first Haiku model with an adjustable effort setting, a dial that lets users trade cost for smarter answers. Anthropic also halved Sonnet 5.5's cache-read price to $0.10 per million tokens, the discounted rate for text a model has already processed.
BitcoinBTC · USD
$83,432−0.29%
Sep 30Oct 2Oct 4Oct 6Oct 7
$86.8k$85.5k$84.3k$83.0k
24h HighHigh$85,643
24h LowLow$82,823
VolVol$1.7B
Market projectionsOdds by Myriad
Today$82,000 to $84,000$82k–$84k54% chanceThis weekBelow $84,000Below $84k60% chance
 →
Buy Bitcoin with USDT
Powered by Jupiter
Haiku 5.5 comes 15 days after Opus 5.5 on September 22 and nine days after Sonnet 5.5 on September 28, the last of the three Claude 5.5 models Anthropic had promised. Opus 5.5 was the first release since CEO Dario Amodei published an essay urging the industry to slow gains in AI capabilities.
Haiku 5.5 is available now on the Claude website, Amazon Web Services, Google Cloud and Microsoft Azure under the name claude-haiku-5-5. Anthropic is also rolling out monthly API credits this week: $100 for subscribers on the Max 5x plan, $200 for Max 20x, and up to $500, pooled across users, for Team plans.